For the last two years, the AI industry has been obsessed with making models "smarter" and more "agentic," but the underlying tools for developers have remained largely the same. We've been forcing general-purpose LLMs to act like classifiers using function calling and JSON mode—a workaround that was never their primary design.
The Simple Version
Imagine you are running a massive customer support center. Currently, you hire highly educated professors (General LLMs like GPT-4 or Claude Opus) to read every single email just to decide if it's a billing question or a technical one. It works, but it's incredibly expensive and slow because you're using a genius to do a simple sorting task.
Jev is like hiring a specialized, lightning-fast sorting machine instead. It doesn't try to write poetry or solve complex math; its entire existence is dedicated to looking at an input and instantly categorizing it into specific buckets.
How It Works
Unlike traditional LLMs that treat structured output as a "second property" or an afterthought, Jev is built from the ground up for classification. It takes a pre-trained language model and adds a specialized training layer at the end to ensure it strictly adheres to classification tasks.
The Three Core Data Types
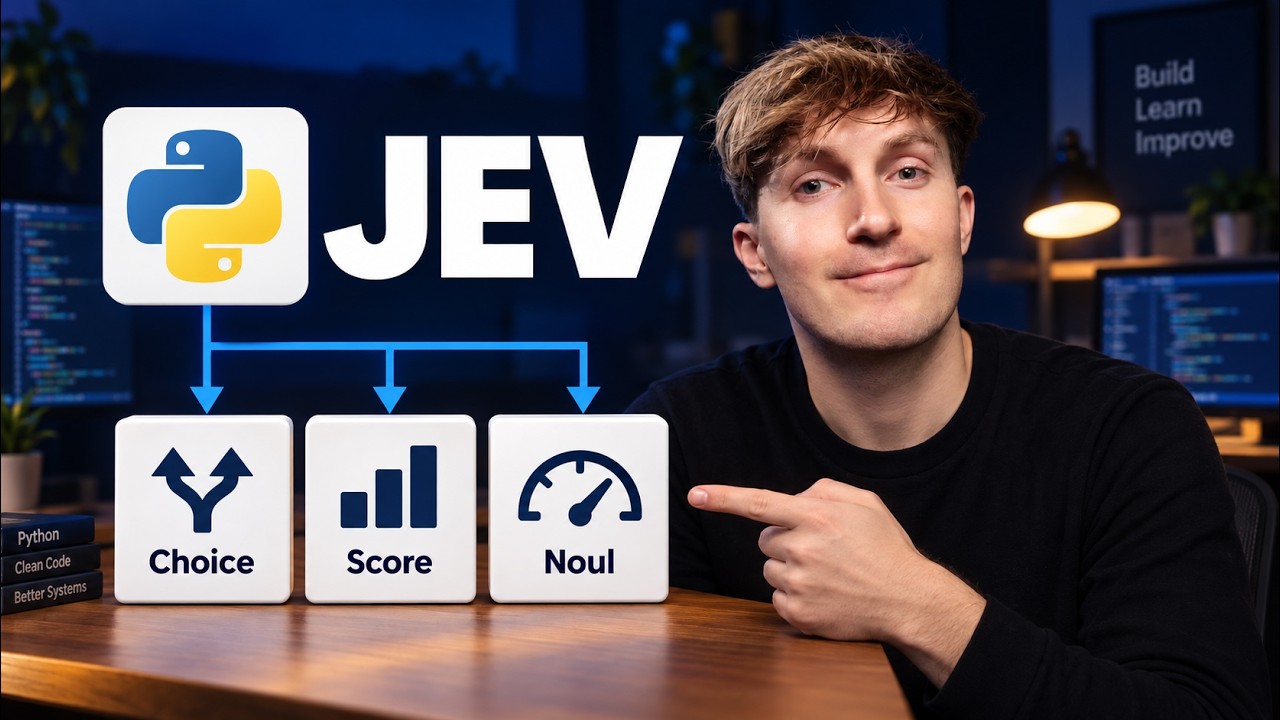
As Dave Ebbelaar demonstrates, the Jev SDK revolves around three distinct ways to extract information from a "state" (the input text):
- Choices: You provide a list of specific categories (e.g., "billing", "technical", "other"). The model picks the best match and returns it along with a confidence score.
- Scores: Instead of picking just one, the model provides a probability distribution across a list of criteria. This is perfect for measuring things like "frustration levels" where a user might be both "frustrated" and "civil."
- Nulls: This is essentially a Boolean (Yes/No) check. It returns the probability of a condition being true, such as "Does the customer explicitly ask for a refund?"
Batching with Single API Calls
One of the most powerful features for developers is the ability to combine these types into a single request. You can ask for a Choice (the department), a Score (the sentiment), and a Null (the refund request) all at once. This reduces latency and complexity by turning multiple logic steps into one clean, programmatic response.
Technical Deep Dive
From an architectural standpoint, Jev represents a departure from the standard "System Prompt + User Prompt + JSON Schema" workflow. In a standard OpenAI or Anthropic implementation, you spend significant tokens and latency managing complex system instructions to keep the model within the bounds of your desired JSON schema. This is often fragile and prone to "hallucinating" extra text.
Jev uses a more declarative approach. Because the model is optimized for classification, the API doesn't require massive system prompts to enforce structure. Instead, you provide the input state, the question, and the criteria. The underlying model architecture is fine-tuned to map these inputs directly to the probability distributions of your defined classes.
For example, when performing a Score operation, the model isn't just generating text that looks like a number; it is outputting a probability distribution over the provided categories. This makes it mathematically robust for developers to use in if/else statements or routing logic. As Ebbelaar notes, this allows for more granular "leaf node" decisions in complex AI workflows, where you can branch your application based on highly specific, high-confidence classification results.
Why This Matters
The economic implications for production AI applications are massive. During his comparison, Ebbelaar highlights a staggering cost difference: performing 100,000 requests (with 500 input tokens each) would cost roughly $2 using Jev, compared to $50 using Claude Haiku. That is a 25x reduction in operational costs.
For developers, this enables a new design pattern: The Router Pattern. Instead of sending every user interaction to an expensive reasoning model (like Claude Opus or GPT-4o), you use Jev as a high-speed, low-cost router. Jev classifies the intent, and only if the task is complex does the system escalate the request to a larger, more expensive model.
While Jev is a new player in a market currently dominated by giants, it signals a shift toward specialized, task-oriented models. As Ebbelaar predicts, "I think this is going to kick off a new trend." Whether through specialized APIs like TypeSafe or through smaller, self-hosted open-source models, the future of AI applications lies in moving away from "one model to rule them all" and toward highly efficient, specialized classification layers.