Managing a few GPU servers is easy, but routing millions of requests across global clusters while keeping latency low is a nightmare. When a single routing decision can either reuse a massive cache or force a costly recomputation, the stakes for load balancing become incredibly high.
The Simple Version
Imagine you are managing a fleet of taxis across a city. In the old system, you just told drivers to go where they saw the most people waiting. If one street got crowded, drivers rushed there; once the crowd cleared, they all left at once, leaving the street empty again. This constant "bouncing" created chaos.
OpenAI's new system is like having a central air traffic control tower with a God-eye view of the whole city. Instead of drivers reacting to what they see in the moment, the tower calculates the best move for everyone based on traffic, distance, and how many passengers each taxi can actually hold.
How It Actually Works
The system, known as the Inference Load Balancer (IRB), sits between CPU-based front-end clusters (the gateways) and GPU-based engine clusters (where the models live). Its job is to select the best engine for a request and proxy it there.
The Control Plane vs. The Data Plane
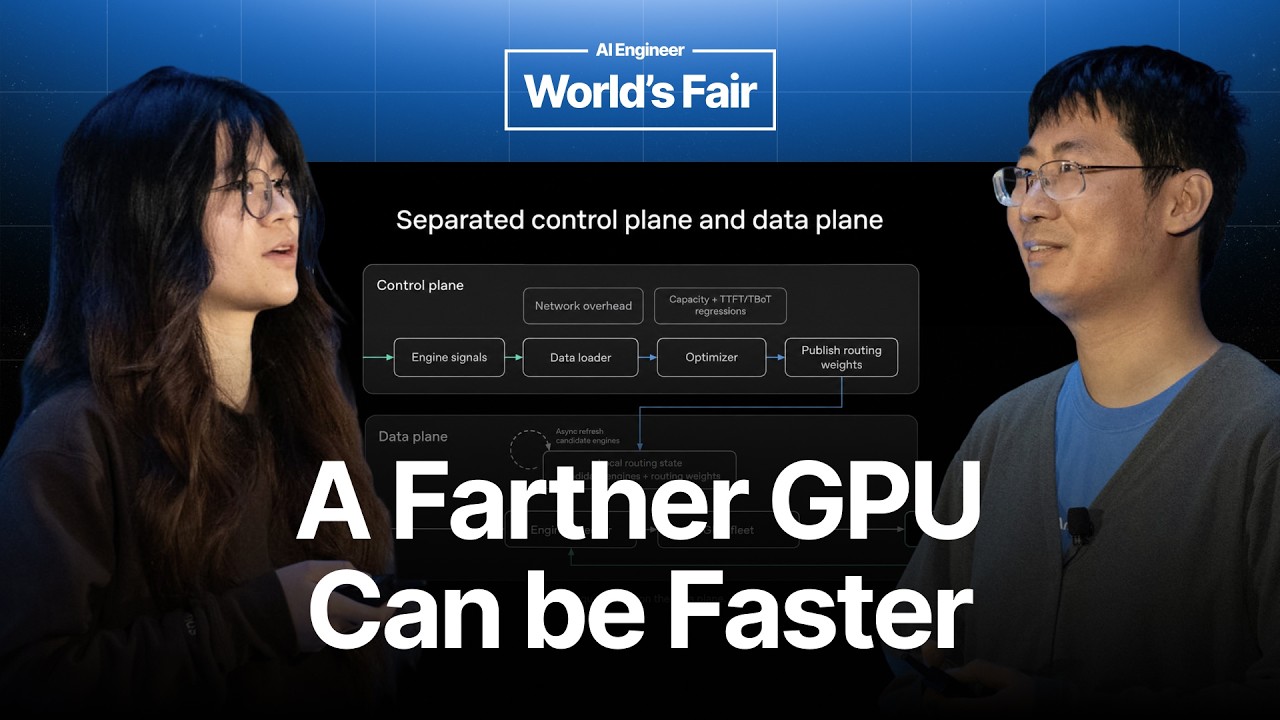
To avoid the lag of asking a central server for every single request, OpenAI split the architecture into two parts. The control plane maintains a global view of every CPU cluster and GPU engine, calculating the optimal routing weights asynchronously.
The data plane lives inside each CPU cluster. It doesn't do complex math; it simply looks at a cached snapshot of routing weights provided by the control plane and makes a split-second decision on where to send the request.
The Three-Path System
The architecture operates via three distinct data flows. First is the inference request path, which is the only synchronous part: the request arrives, the data plane checks the local weight cache, and the request is forwarded.
Second is the engine signal path. Engines continuously report real-time metrics like Time to First Token (TTFT) and Time Between Tokens (TBOT). These signals flow back to both the control plane (for global optimization) and the data plane (for fast local guards).
Third is the routing weight path. The control plane processes the signals through an optimizer and publishes new weights, which the data planes pull into their local caches periodically.
Technical Deep Dive
To understand why this change was necessary, we have to look at the KV (Key-Value) Cache. In LLM inference, the model stores the mathematical representations of previous tokens in a cache so it doesn't have to re-process the entire conversation history for every new token generated. If a follow-up request is routed to a different engine, that cache is lost, forcing the model to recompute everything, which spikes latency and wastes GPU cycles.
OpenAI's early system used weighted consistent hashing. This is a technique where requests are mapped to a "ring" of servers; it ensures that if a server is added or removed, only a small fraction of keys are remapped. However, the weights for this hashing were determined by a proportional controller (a P-controller).
As Lu Zhang explains, this feedback loop would nudge weights up or down based on how an engine's performance compared to the fleet average. The problem was oscillation: if the controller shifted traffic away from a "hot" engine, that engine would cool down. The controller would then see the spare capacity and slam traffic back onto it, which, as the team noted, "wrecks the KV cache locality routing was meant to protect."
The Global Optimizer
The new optimizer replaces the simple loop with a mathematical goal: minimize the expected end-to-end latency across all traffic. It considers four primary inputs: request volume per CPU cluster, network latency, available engine capacity/health, and latency profiles (how TTFT and TBOT increase as load rises).
Crucially, the optimizer recognizes that the "nearest" engine isn't always the fastest. Qianru Lao provides a concrete example: if a CPU cluster in Region A sends 120 requests per second (RPS) but the local engine can only handle 100 RPS, those extra 20 requests will queue up. If an engine in Region C has 40 RPS of spare capacity, routing those 20 requests to Region C—despite the higher network distance—is faster than making them wait in a queue in Region A.
The optimizer solves this under three hard constraints: all traffic must be routed, no engine can exceed its effective capacity, and routing weights must remain non-negative.
Why This Matters
This shift from reactive feedback to explicit policy solves the "black box" problem of production AI. In the old system, it was nearly impossible to explain why a specific engine had a certain weight or to tune one property without accidentally breaking another.
Furthermore, the system introduces critical stability protections. To prevent "retry storms"—where failures trigger retries that further overload a struggling system—OpenAI implemented dynamic retry budgets that tighten as utilization increases.
Finally, the inclusion of load shedding ensures that when demand exceeds total global capacity, the system degrades gracefully by proactively dropping a portion of traffic rather than allowing the entire inference fleet to crash under the pressure.