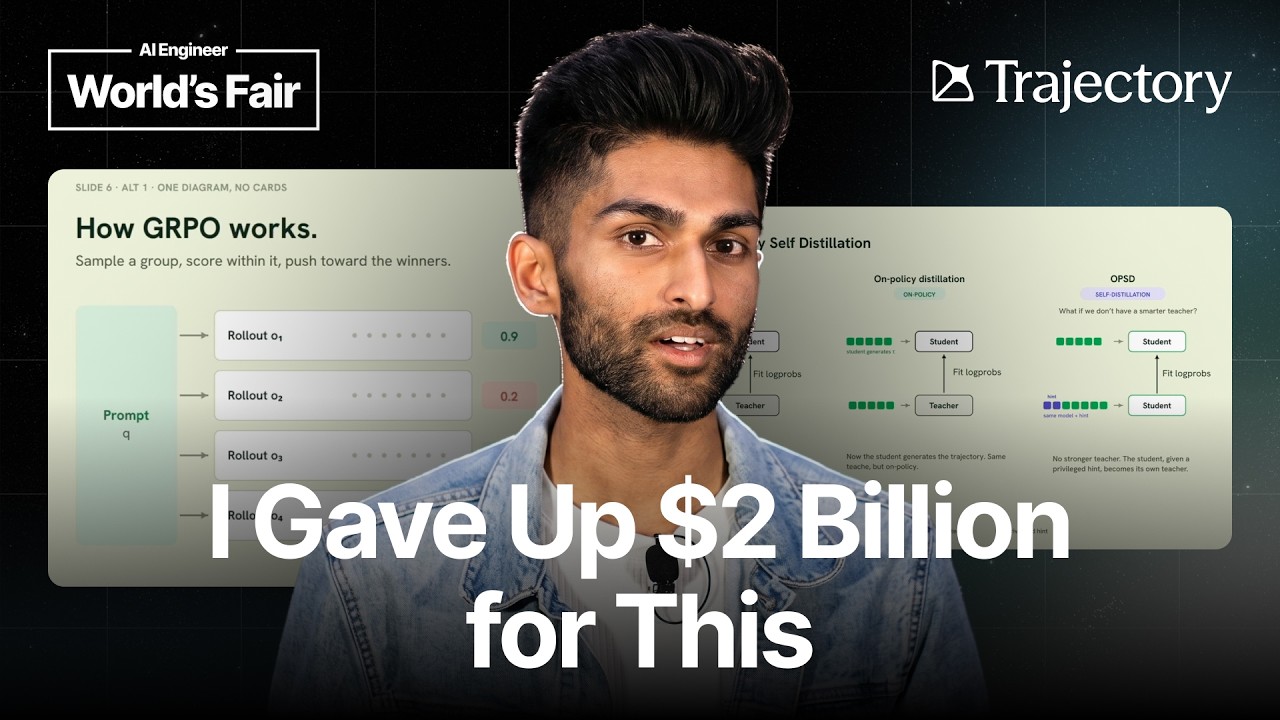
Ever wonder why a super‑smart AI starts answering everything with ‘maybe’? Ronak Malde explains the odd ‘but wait’ collapse that happens when models learn from their own hints.
The Simple Version
Think of a student trying to copy a teacher’s answers, but the teacher keeps correcting every tiny mistake. If the student strays too far, the teacher pulls it back, leaving the student stuck between two different ways of answering.
How It Actually Works
The core trick
Instead of using a bigger external teacher, the model becomes its own teacher. A special hint is added to the teacher’s prompt, and the student learns to match the teacher’s log‑probabilities for tokens it never actually saw.
The four evaluation rules
Malde checks each method on (1) online task changes, (2) on‑policy sampling, (3) no parallel rollouts, and (4) per‑token reward. He pits SFT, RLHF, GRPO, and self‑distillation against these.
Why self‑distillation wins
It optimizes the whole vocabulary at each step, not just the top token, so the model keeps improving even when GRPO plateaus.
Technical Deep Dive
The loss mixes standard cross‑entropy with a KL term that scales per step, and a residual term that nudges away from leaked hints.
Step‑level KL weighting handles divergence between student and teacher distributions, while residual guidance prevents hint leakage that would otherwise turn the model into a reward‑hacking loop.
Why This Matters
If you’re building agents that make long tool‑call chains, avoiding the ‘maybe’ trap means more reliable automation and less compute waste.
It also shows how to safely reuse huge models without needing a bigger external teacher, a key step toward practical continual learning at frontier scales.
Key Takeaways
- Self‑distillation lets a model teach itself using privileged hints.
- It evaluates on four strict properties: online distribution, on‑policy sampling, no parallel rollouts, per‑token reward.
- GRPO collapses feedback into a single sequence‑level score, while self‑distillation optimizes per token.
- Failure modes such as hint leakage and step‑level KL weighting are useful design signals.
- The approach scales to 120B models and hundred‑tool‑call trajectories.
- Real‑world impact: more reliable autonomous agents and cheaper training at the frontier.