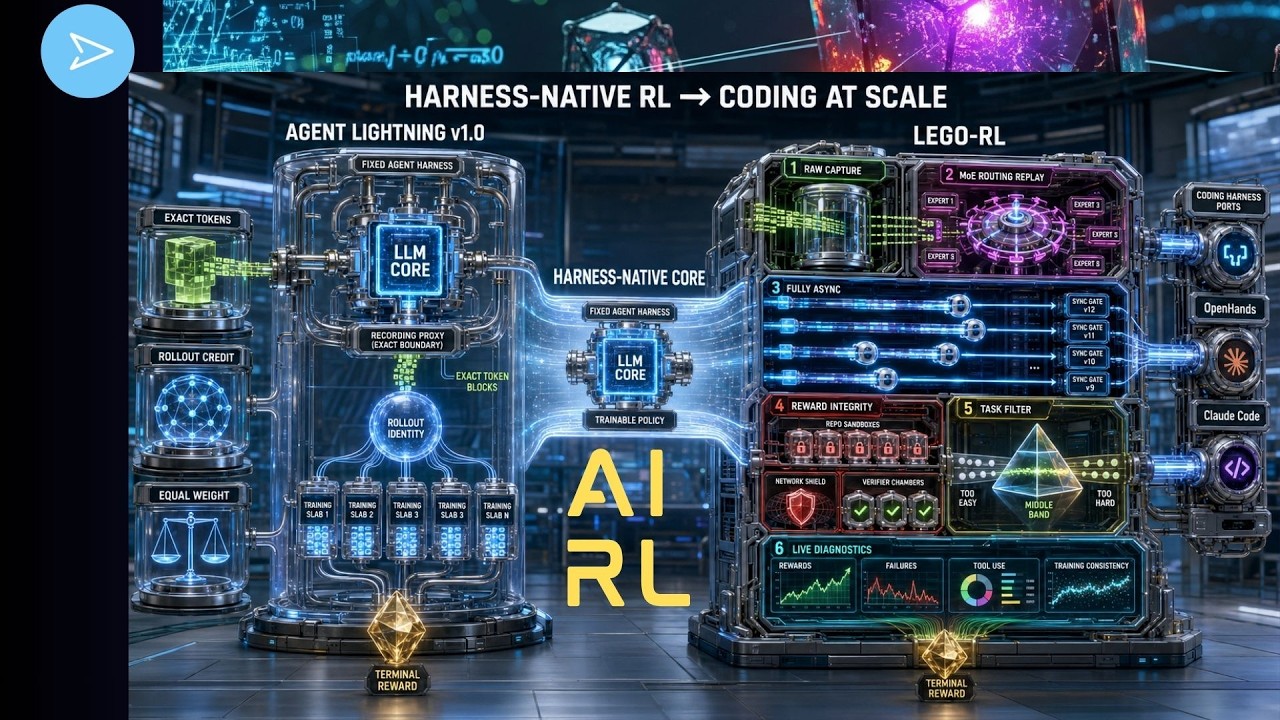
Agentic Lightning V1 just dropped a breakthrough that lets AI agents think several steps ahead, just like a chess player plotting multiple moves.
The Simple Version
Think of an AI agent as a robot explorer trying to find treasure in a maze.
How It Actually Works
Mathematical Fix
Traditional RL uses expected reward sums, but they can be unstable.
Agentic Lightning V1 introduces a variance‑reduced objective that converges faster.
Agentic Loop
The agent repeatedly predicts a goal, plans a sequence, and executes it.
Each step updates the policy based on observed outcomes.
Technical Deep Dive
Under the hood, the paper proposes a λ‑return estimator that blends multi‑step returns with bootstrapping.
Implementation uses PyTorch tensors and automatic differentiation to keep gradients stable.
Training runs on NVIDIA GPUs with mixed‑precision to speed up convergence.
Why This Matters
Better planning means AI can handle tasks that require long‑term strategy, like robotics or autonomous driving.
Enterprises can deploy agents that negotiate deals or manage supply chains with less human oversight.
Researchers gain a stable framework to experiment with true agentic behavior.
Key Takeaways
- Agentic Lightning V1 fixes core RL math for stable multi‑step planning.
- It enables AI agents to generate and follow goal‑directed plans.
- The method reduces variance while keeping computational cost manageable.
- Open‑source code will be released on GitHub for community experimentation.
- Potential impact spans robotics, finance, and personalized AI assistants.
- Developers can integrate the approach using simple PyTorch modules.
- Future work aims to combine this with large language model reasoning.