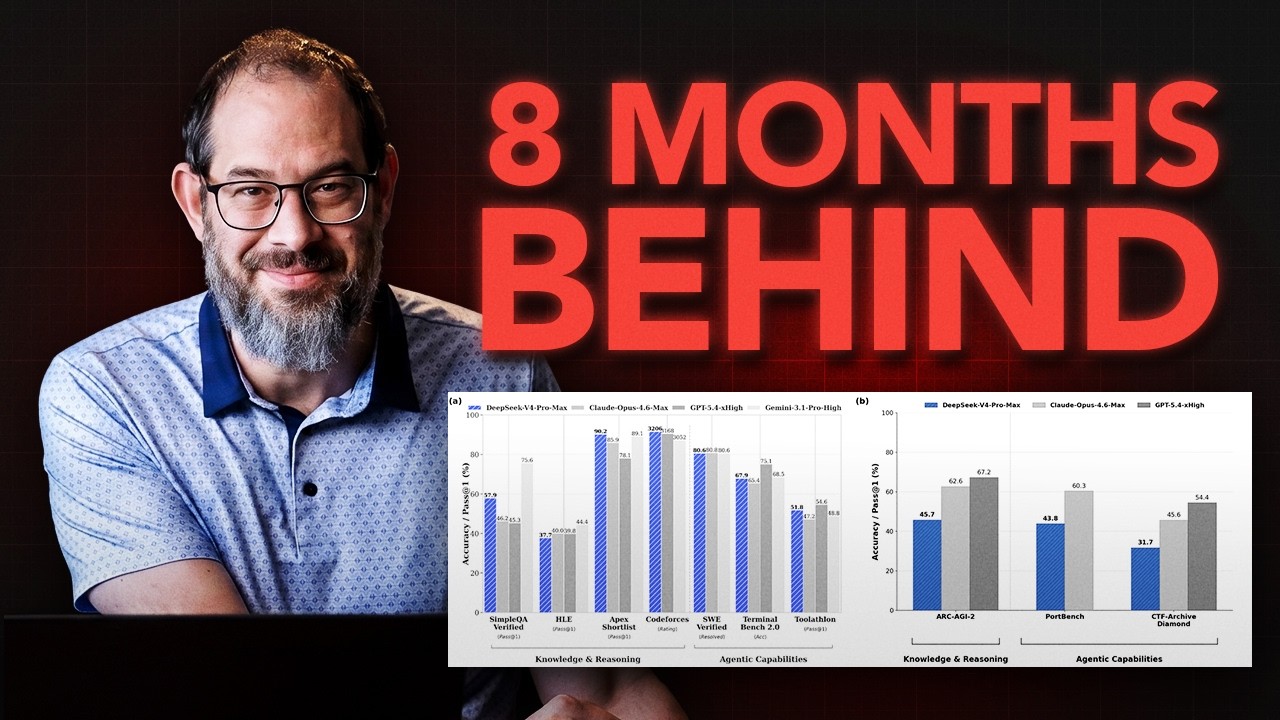
Ever wonder why a model priced at 87¢ can end up costing you more than a $15 alternative?
The price tag alone hides crucial factors that decide if a model is truly cheap.
The Simple Version
Think of AI model pricing like buying a printer: the machine might be cheap, but ink, paper, and maintenance add up. The same goes for LLMs — what you pay for tokens is only part of the story.
How It Actually Works
Why token price and finished work cost point in opposite directions
Token pricing looks cheap, but the total cost of a completed task can explode when you factor in latency, error correction, and scaling.
How mixture-of-experts changes what your hardware actually has to hold
Mixture‑of‑Experts (MoE) models split functionality across many specialist sub‑networks, so only a few experts activate per token. This reduces per‑token compute but requires you to keep the full weight set in memory, inflating RAM needs.
What the CAISI evaluation found about DeepSeek V4 Pro economics
The CAISI study measured cost per accepted result across different workloads, revealing that DeepSeek V4 Pro can be cheaper for high‑volume, well‑defined tasks but expensive for open‑ended generation.
Technical Deep Dive
API vs self‑host trade‑offs
When you call an API you pay per token and rely on the provider’s rate limits, but you avoid managing GPUs. Self‑hosting gives full control over batching and quantization, yet you must provision enough VRAM for the entire model.
Distillation and capability spread
Distillation creates smaller models by mimicking larger ones, which can lower cost but may sacrifice accuracy on edge cases. The legal fight centers on whether distilled data respects the source model’s license.
Mixture‑of‑Experts memory footprint
Even if only 2‑4 experts fire per token, the full expert matrix can require 100‑200 GB of GPU memory, forcing you to choose between smaller MoE variants or aggressive quantization.
Why This Matters
Chinese LLMs are reshaping the cost curve for AI startups, letting them run massive workloads at a fraction of Western prices.
But when a single mistake can cost thousands, the apparent savings vanish, making careful evaluation essential.
Understanding these nuances helps engineers avoid hidden budget traps and choose the right deployment strategy.
Key Takeaways
- Price per token ≠ total cost of a completed task.
- Mixture‑of‑Experts reduces per‑token compute but inflates memory usage.
- High‑volume, checkable work favors Chinese models; creative or risky tasks do not.
- Self‑hosting gives control but demands substantial hardware resources.
- Distillation can lower cost but may breach licensing agreements.
- API services hide latency and error‑handling expenses.
- Always run the four evaluation questions before committing.